
A non-human identity (NHI) is any identity that a machine, workload or automated process uses to authenticate, rather than a person. Service accounts, IAM roles, service principals, managed identities, API keys, access keys and certificates are all non-human identities, and so, increasingly, are AI agents.
Most definitions stop at that list. This guide goes one step further, because “service account” means three different things in AWS, Azure and Google Cloud. It covers what a non-human identity actually is in each cloud, where AI agents fit, and how to inventory the ones you already have.
Non-human identity, machine identity, workload identity: are they the same?
Mostly, yes. The industry uses these terms loosely and often interchangeably, and vendors tend to draw the lines wherever their product starts and stops. It helps to know how the main sources use them.
| Term | How it is usually used | Example of use |
| Non-human identity (NHI) | The broadest term: any identity that is not a person | The OWASP Non-Human Identities Top 10 (2025) uses it for identities that applications and software need |
| Machine identity | Often used the same way as NHI; sometimes used narrowly for certificates and cryptographic keys | Microsoft groups workload identities and device identities together as “machine (or non-human) identities” |
| Workload identity | An identity assigned to a piece of running software: an application, service, script or container | Microsoft Entra Workload ID; GKE Workload Identity Federation; AKS workload identity |
| Service account | A product name, not a category. It means different things in different systems | A GCP service account is a cloud principal; a Kubernetes service account is a pod identity; an Active Directory service account is a user account used by software |
A working rule: non-human identity is the umbrella. Machine identity is a near-synonym, with some writers reserving it for certificates and keys. Workload identity is the subset attached to running software, which in practice is where most cloud risk sits.
This guide uses “non-human identity” for the whole category and “machine identity” or “workload identity” where it is talking about a specific kind. None of these definitions is wrong. What matters is being clear about which objects you are counting.
What a non-human identity actually is, in each cloud
The same idea, “software proving who it is”, is built differently in each cloud. The table below maps the main mechanisms to the real object names you will see in the console and in the logs.
| Mechanism | AWS | Azure | GCP |
| Identity attached to compute, no stored secret | IAM role through an instance profile, Lambda execution role, ECS task role | Managed identity, system-assigned or user-assigned | Service account attached to a VM, Cloud Run service or Cloud Function |
| Kubernetes pods | EKS Pod Identity, or IAM roles for service accounts (IRSA) using AssumeRoleWithWebIdentity | AKS workload identity (a federated credential on a managed identity or app) | GKE Workload Identity Federation |
| Federation from outside the cloud (CI, other clouds, on-premises) | IAM OIDC and SAML identity providers; IAM Roles Anywhere for X.509 certificates | Federated identity credentials on an app registration or user-assigned managed identity | Workload identity pools and providers, with STS token exchange |
| Long-lived secrets | IAM user access keys (beginning AKIA); Bedrock long-term API keys, which AWS backs with an IAM user it creates | App registration client secrets and certificates; Azure OpenAI and AI Services account keys; storage account keys | Service account JSON keys; API keys, including Gemini API keys |
| One identity acting as another | sts:AssumeRole, role chaining, iam:PassRole | App role assignments to service principals; RBAC role assignments | Service account impersonation through roles/iam.serviceAccountTokenCreator; iam.serviceAccountUser (actAs) |
The first row is the one to move towards. When an identity is attached to compute, the cloud issues short-lived credentials to the workload and rotates them automatically. On AWS these are temporary keys beginning ASIA. Nothing is written to a file, so there is nothing to leak from a repository or a laptop.
The fourth row is the one to move away from. Long-lived secrets stay valid until someone rotates or deletes them. They get copied into configuration files, notebooks, CI variables and, more recently, the configuration files of Model Context Protocol (MCP) servers. Every copy is a place the secret can leak from.
Two details in the table catch people out. A GCP API key identifies a project, not a principal, so a log entry for a call made with one tells you which project paid but not who made the call. And an Azure OpenAI account key bypasses Microsoft Entra ID entirely: using the key is not an Entra sign-in, so it never appears in sign-in logs.
AI agents are the newest class of non-human identity
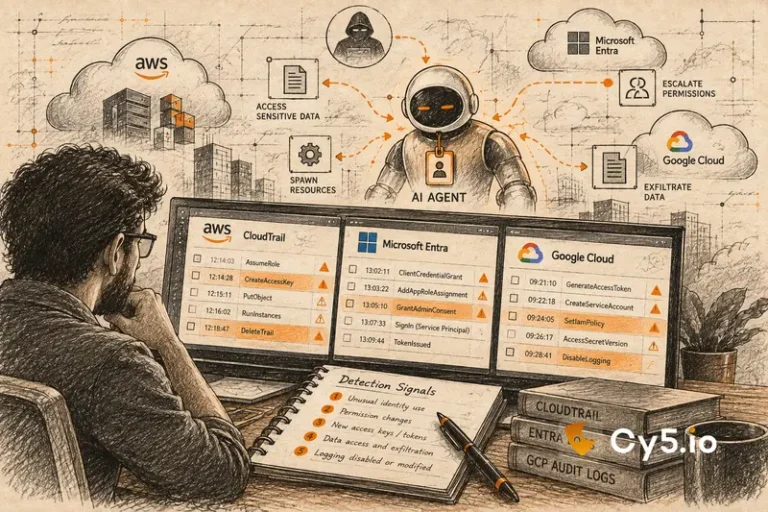
An AI agent needs credentials to do anything useful. It has to call a model, read a knowledge base, query a database or use a SaaS tool. Each of those calls is made with some identity, and the cloud records that identity, not the agent.
In most organisations today, that identity is ordinary. It is an IAM role, a service principal or a service account created for a pilot, often with broad permissions so that nothing breaks. From the cloud’s point of view, nothing marks it as belonging to an agent.
All three providers now offer a purpose-built alternative:
- AWS: Amazon Bedrock AgentCore Identity gives an agent a dedicated workload identity, an inbound authorizer, and outbound credential providers with a token vault for the OAuth tokens and API keys the agent uses with third-party tools.
- Azure: Microsoft Entra Agent ID, generally available since April 2026, introduces agent identity blueprints, agent identities and agent users, each with owners and sponsors.
- GCP: Agent Identity for Vertex AI Agent Engine gives each deployed agent its own SPIFFE-based principal, with short-lived X.509 certificates and bound tokens. Unlike a shared service account, it cannot be impersonated.
Entra Agent ID is the first native “this principal is an agent” label on any of the three clouds. The limitation is that it applies only to agents built on it. A custom agent running on an ordinary service principal is still invisible as an agent. The same is true on AWS and GCP: the new identity types help for agents that use them, and do nothing for the agents already running on plain roles and service accounts.
MCP servers add a further layer. An MCP server sits between the agent and the API: the agent talks to the server, and the server calls the cloud or SaaS API with its own credentials. In other words, MCP servers act as identity brokers [/blog/mcp-server-security/], and every agent behind one server looks like the same actor in the downstream logs.
For banks and NBFCs in India, this has a regulatory angle. The RBI’s FREE-AI committee report suggests extending the access control provisions of the RBI’s 2023 Master Direction on IT governance to cover autonomous AI. The committee does not use the phrase “non-human identity”, but access control for an AI system in the cloud is exactly that: control over the identity the system runs as. Our guide to the RBI FREE-AI framework [/blog/rbi-free-ai-framework/] covers this in more detail.
Why non-human identities are harder to govern than user accounts
Human identities have a lifecycle that most organisations run well. People join, move and leave, and HR systems trigger each step. Non-human identities have no equivalent.
There is no leavers process. When an employee leaves, their account is disabled. When a project ends, a vendor contract lapses or an AI pilot finishes, nobody is told to remove the identities it created. They stay, often with the access they had on the last day.
Permissions are written broadly. Machine identities are usually created by engineers under time pressure, and the easiest way to avoid a permissions error is to grant more than needed. AI agents make this worse, because an agent chooses its tools at run time and nobody knows in advance exactly which calls it will make.
Credentials get copied everywhere. A human’s password lives in their head and a password manager. A machine’s secret lives in whatever file or variable someone put it in: a config file, a notebook, a CI secret, an MCP configuration. Each copy is an exposure that the identity’s owner may not know about.
And there is often no owner a system can read. A user account has a named person attached. A service principal or IAM role often has nothing: no owner tag, no team label, no ticket reference. When something goes wrong, finding who is responsible means asking around.
The OWASP Non-Human Identities Top 10 reflects the same problems: improper offboarding, secret leakage, over-privileged identities and long-lived secrets are all on its list.
How to inventory the non-human identities you already have
An inventory does not need a new tool to start. Each cloud exposes the data through APIs you already have access to.
On AWS, GetAccountAuthorizationDetails returns every IAM user, role, group and policy in an account, with their attached and inline policies and role trust policies. The IAM credential report (GenerateCredentialReport, then GetCredentialReport) lists every IAM user with the age and access_key_last_used_date of each access key. For roles, GetRole returns RoleLastUsed. Run these per account, or through a delegated administrator across an organisation.
On Azure, list service principals through Microsoft Graph and separate managed identities from app registrations by their servicePrincipalType. Pull RBAC role assignments across subscriptions with Azure Resource Graph. Use the Entra audit logs for who created each identity and when, and the service principal and managed identity sign-in logs for when each was last used.
On GCP, Cloud Asset Inventory can search every service account and every IAM policy binding across an organisation. IAM Recommender and Policy Intelligence Activity Analyzer show which service accounts and keys have authenticated recently and which have not.
Against each identity, record three things:
- Who owns it, recorded as a tag, label or owner field that a script can read.
- When it was last used.
- What it can reach, especially data stores and the ability to create or change other identities.
That short record answers most of the questions an auditor or incident responder will ask. Identities with no owner, no use in 90 days and admin-level access are the first to review.
Common questions about non-human identities
AWS IAM roles and access keys, Azure service principals and managed identities, GCP service accounts and service account keys, API keys, OAuth client credentials, TLS certificates, Kubernetes service accounts, CI/CD pipeline identities and AI agent identities.
A service account is one type of non-human identity. “Non-human identity” is the whole category; “service account” is a product term whose meaning depends on the system, and it means something different in GCP, Kubernetes and Active Directory.
Yes. Every AI agent authenticates as some identity to reach models, data and tools. Usually that is an ordinary role, service principal or service account; newer services such as Entra Agent ID, AgentCore Identity and Vertex AI Agent Identity create identities built specifically for agents.
It varies too much for any single number to be useful, and the published ratios of machine to human identities come from vendor surveys rather than independent measurement. Count your own: the inventory calls above give you an exact figure for each cloud account in an afternoon.
What this looks like with a platform
The inventory method above works. The problem is keeping it current across dozens of accounts, subscriptions and projects, and joining it into one picture. A spreadsheet built this quarter is out of date by next quarter, and it shows each identity in isolation.
Cy5’s ion platform keeps that inventory live. Its entity graph records human and machine identities, workloads, APIs and data stores across AWS, Azure and GCP, together with the relationships between them: which workload runs as which identity, which identity can assume which role, and which data stores each can reach. Its CIEM view compares the permissions each identity has been granted with the ones it has actually used, so over-privileged identities stand out. More detail is on the Cy5 identity and CIEM page [[CY5 CIEM PAGE URL]].
Where to start, and what an inventory cannot tell you
Three steps give most teams a useful first picture:
- Run the inventory calls above for every cloud account, subscription and project, and put the results in one place.
- Find every long-lived secret: IAM user access keys, client secrets, service account keys and API keys. Replace the ones you can with identities attached to compute.
- Tag every remaining identity with an owner, and review anything unowned and unused for 90 days.
Be clear about the limits. An inventory built from policy and asset APIs shows what exists and what it is permitted to do. It does not show why an identity exists or what it is for. It also cannot tell you which identities belong to AI agents, unless the cloud labels them, which today happens only for agents built on the new agent identity services. For the rest, that link has to come from tagging and naming discipline. For what those identities do once they are running, see our guide to securing the AI agents that run on these identities [/blog/ai-agent-security/], and for the wider picture, the anatomy of an identity-driven cloud attack surface [/blog/anatomy-of-an-identity-cloud-attack-surface-cy5/].